Backpropagation in Machine Learning: How It Works, Formula & Example
By upGrad
Updated on Oct 14, 2026 | 6 min read | 24.35K+ views
Share:

All courses
Certifications
More
By upGrad
Updated on Oct 14, 2026 | 6 min read | 24.35K+ views
Share:
Table of Contents
Quick Insights:
Interested in learning how machine learning works? Explore real-world ML applications, and build practical skills with Machine Learning Courses Online. Start your journey towards a career in AI and machine learning now!
Popular AI Programs
Backpropagation in machine learning is a method used to train neural networks. It helps the network learn from its mistakes and improve its predictions. Without backpropagation, training a network with millions of weights would take much longer.
Backpropagation is short for “backward propagation of errors.” It is a core algorithm used to train neural networks.
A neural network makes predictions using weights and biases. Backpropagation calculates how much each weight and bias affects the prediction error. It does this by working backward from the output layer to the input layer. It uses a math rule called the chain rule to calculate these changes.
| Rumelhart, Hinton, and Williams explained this method in a 1986 research paper. Today, it is still used to train neural networks. |

In simple words:
A neural network has many connected parts, and each weight can affect its final prediction. Backpropagation helps train the network by solving three main problems:
Backpropagation and gradient descent work together, but they do different jobs. Backpropagation calculates the gradients, while gradient descent uses them to update the weights and reduce the loss.
Free Courses
Backpropagation works in four steps. The neural network makes a prediction, checks its error, finds which weights need to change, and updates them. This process repeats until the network makes better predictions.

The loss tells us how far the prediction is from the correct answer.
Mean squared error is used for many number-based predictions. Cross-entropy is used for many classification tasks.
AI Courses to upskill
Explore Artificial Intelligence Courses for Career Progression
The backpropagation formula helps a neural network find how much each weight affects the error. It uses the chain rule to calculate this effect. Gradient descent then uses these results to update the weights.
The chain rule helps find how much a small change in a weight affects the final error. It breaks the calculation into smaller steps.
The formula is:
(Lw=Laazzw)
In simple words, this formula checks three things:
1. For an output neuron using the sigmoid activation function and squared error loss, the error signal is:

Here, the error signal shows how much the loss changes when the neuron's weighted sum changes.
2. The gradient for a weight connected to this output neuron is
Lw=outaprev

This means the gradient is the error signal multiplied by the output of the previous neuron.
Also Read: Accuracy Formula in Machine Learning
3. For a hidden neuron, backpropagation uses the error signals from the next layer to calculate its own error signal:
hidden=kwkka(1-a)

This helps the network find how much each hidden neuron contributes to the final error.
After calculating the gradient, the network updates its weights using gradient descent.
The formula is:
wnew=wold-Lw
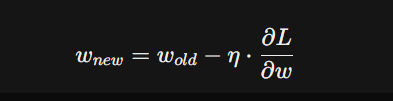
In simple words:
The network subtracts the gradient from the current weight, multiplied by the learning rate. This helps reduce the loss during training.
Biases are updated in a similar way. The main difference is that the bias update uses the error signal directly.
Also Explore: RMSE in Machine Learning: Formula, Calculation, and Real-World Use
The formulas use a few symbols to explain how backpropagation works. Here is what each symbol means.
| Symbol | Meaning |
| L | Loss (error) for the current example |
| w | A weight connecting two neurons |
| z | Weighted sum of inputs plus bias, before activation |
| a | Activation: the neuron's output after the activation function |
| y | True target value |
| δ (delta) | Error signal at a neuron: ∂L/∂z |
| a_prev | Activation of the neuron feeding into the weight |
| η (eta) | Learning rate: how big each update step is |
| ∂L/∂w | Gradient: how much the loss changes when w changes |
The backpropagation algorithm helps a neural network learn from its mistakes. It follows a set of steps to find errors, calculate how much each weight affects them, and update the weights. The network repeats these steps many times to improve its predictions.
Also Read: How to Implement Machine Learning Steps: A Complete Guide

Backpropagation and gradient descent work together, but they have different jobs.
The learning rate controls how big each weight update will be. Other optimizers, such as SGD, Momentum, RMSprop, and Adam, use gradients in different ways. Backpropagation calculates the gradients they need.
During backpropagation, the network passes gradients through many layers. Sometimes, these gradients become too small or too large.
Some ways to handle these problems include:
Want to learn logistic regression and gradient descent? Explore Executive Diploma in Data Science & AI with IIIT-B program to build your skills and get started!
Let's understand backpropagation with a simple example. We will use a small neural network to see how it makes a prediction, finds the error, and updates its weights.
Our neural network has two input values, two hidden neurons, and one output neuron. Each neuron uses the sigmoid activation function. We will use a learning rate of 0.5 to update the weights.
Here are the values we will use in this example.
| Item | Value |
| Inputs | x1 = 0.5, x2 = 0.8 |
| Target | y = 1.0 |
| Input to hidden 1 | w1 (x1) = 0.15, w2 (x2) = 0.25 |
| Input to hidden 2 | w3 (x1) = 0.20, w4 (x2) = 0.30 |
| Hidden to output | w5 (h1) = 0.40, w6 (h2) = 0.50 |

Step 1: Forward pass.
Step 2: Loss. L = ½(1.0 − 0.6270)² = 0.0696
Step 3: Output error signal.
Step 4: Gradients for the output weights.
Step 5: Push the error back to the hidden layer.
Step 6: Gradients for the hidden weights.
Step 7: Update the weights with w_new = w_old − 0.5 × gradient.
Step 8: Check the result. With the new weights, the network makes a better prediction. Its output increases from 0.6270 to 0.6340, moving closer to the correct answer of 1.0. The loss also drops from 0.0696 to 0.0670. This means the network has made a small improvement. It repeats this process thousands of times to keep improving its predictions.
Are you a working professional and want to accelerate your career? Enroll now in NIRF ranked Ex. Diploma in Machine Learning & AI.
Conclusion:
Backpropagation in machine learning helps a neural network learn from its mistakes. The network makes a prediction, checks how far it is from the correct answer, and finds which weights need to change.
It uses the chain rule to calculate how each weight affects the error. Then, it makes small changes to the weights to improve the next prediction.
Tools like Adam help the network update its weights during training. These tools build on the same basic process.
The 2-2-1 example above helps you understand how backpropagation works step by step. You can try coding the same example in NumPy to practise. You can also use PyTorch, which calculates gradients and runs the backward pass for you.
Want personalized guidance on AI and upskilling? Speak with an expert for a free 1:1 counselling session today.
No, they have different roles in neural network training.
They work together to help a neural network improve its predictions.
The learning rate controls how much a neural network's weights change during training. A high learning rate can make learning faster but may cause the model to miss a good solution. A low learning rate can make training slower. Choosing a suitable learning rate helps the model learn effectively.
The vanishing gradient problem occurs when gradients become extremely small in a deep neural network. This makes it difficult for earlier layers to learn. Techniques such as ReLU activation functions, suitable weight initialisation, and residual connections can help reduce this problem.
Yes, neural network training can slow down or struggle to find better weights. This may happen when the model reaches a flat area of the loss function or a local minimum. Optimisation methods such as momentum and Adam can help improve training.
Backpropagation can work with many activation functions, provided their derivatives can be calculated or suitably handled. Common examples include sigmoid, tanh, ReLU, and GELU. The choice of activation function affects how information and gradients move through a neural network.
No, most machine learning frameworks calculate gradients automatically. Tools such as PyTorch and TensorFlow provide automatic differentiation features for this purpose. However, implementing backpropagation manually can help beginners understand neural network training and learn how these tools work.
Backpropagation is a method commonly used to calculate gradients in neural networks. Automatic differentiation is a broader technique that calculates derivatives by applying mathematical rules to a sequence of operations. Machine learning frameworks use automatic differentiation to perform backpropagation during model training.
Yes, backpropagation is widely used to train deep neural networks. It calculates gradients across the network's layers, helping the model adjust its weights during training. However, very deep networks may face challenges such as vanishing or exploding gradients, which can affect learning.
These methods differ in how much training data they use to update model weights.
Mini-batch gradient descent is commonly used because it balances computational efficiency with frequent weight updates.
Backpropagation is effective for training neural networks, but it has some limitations:
Choosing suitable network designs and training methods can help manage these challenges.
1038 articles published
We are an online education platform providing industry-relevant programs for professionals, designed and delivered in collaboration with world-class faculty and businesses. Merging the latest technolo...
Speak with AI & ML expert
By submitting, I accept the T&C and
Privacy Policy
Top Resources
Master's Degree
18 Months
Executive Diploma
12 Months
IIIT Bangalore
Executive Programme in Generative AI & Agentic AI for LeadersIndia’s #1 Tech University
Dual Certification
5 Months